Your Ethereum node synced for 18 hours, then ran out of disk space at 94%. You resize the volume, restart the sync, and wait another day.
A client update drops. Your Geth version is two minor releases behind. Meanwhile, the team building the actual product is blocked - waiting for a stable RPC endpoint to test against.
This scenario plays out constantly. Teams choose self-hosting for control and cost savings, only to discover that "running a node" and "operating production infrastructure" are fundamentally different problems. Teams that default to managed providers sometimes pay 10x more than necessary, or hit rate limits at the worst possible moment.
The right choice depends on your specific situation: team size, request volume, compliance requirements, chain coverage, and tolerance for operational complexity. This guide breaks down the concrete costs, node requirements measured on Dwellir's own fleet, and operational realities behind each option so you can make that decision with real numbers.
The Fundamental Trade-Off
Self-hosting gives you control. You own the hardware, configure the client software, and set your own rate limits. No third party can throttle your requests, change pricing, or block access to specific regions.
Managed providers give you speed and simplicity. Your first RPC call happens in minutes instead of days. Failover, monitoring, and client upgrades become someone else's problem. You pay per request instead of per server.
The trade-off sounds clean in theory. In practice, both options carry hidden costs that shift the equation. Self-hosting demands ongoing DevOps investment that often exceeds hardware costs. Managed providers introduce dependency on third-party uptime and pricing decisions.
Node requirements by chain, measured on Dwellir's fleet (November 2026)
Running your own node starts with hardware. But hardware requirements vary dramatically by chain, and undersizing any component creates problems that are expensive to fix.
The figures in this section are what Dwellir's production nodes use today, measured on 2026-11-03. Several are well above the minimums client teams publish. Where we know why, the notes below the table say so, and where we do not, we say that too.
How much storage does an Ethereum archive node need?
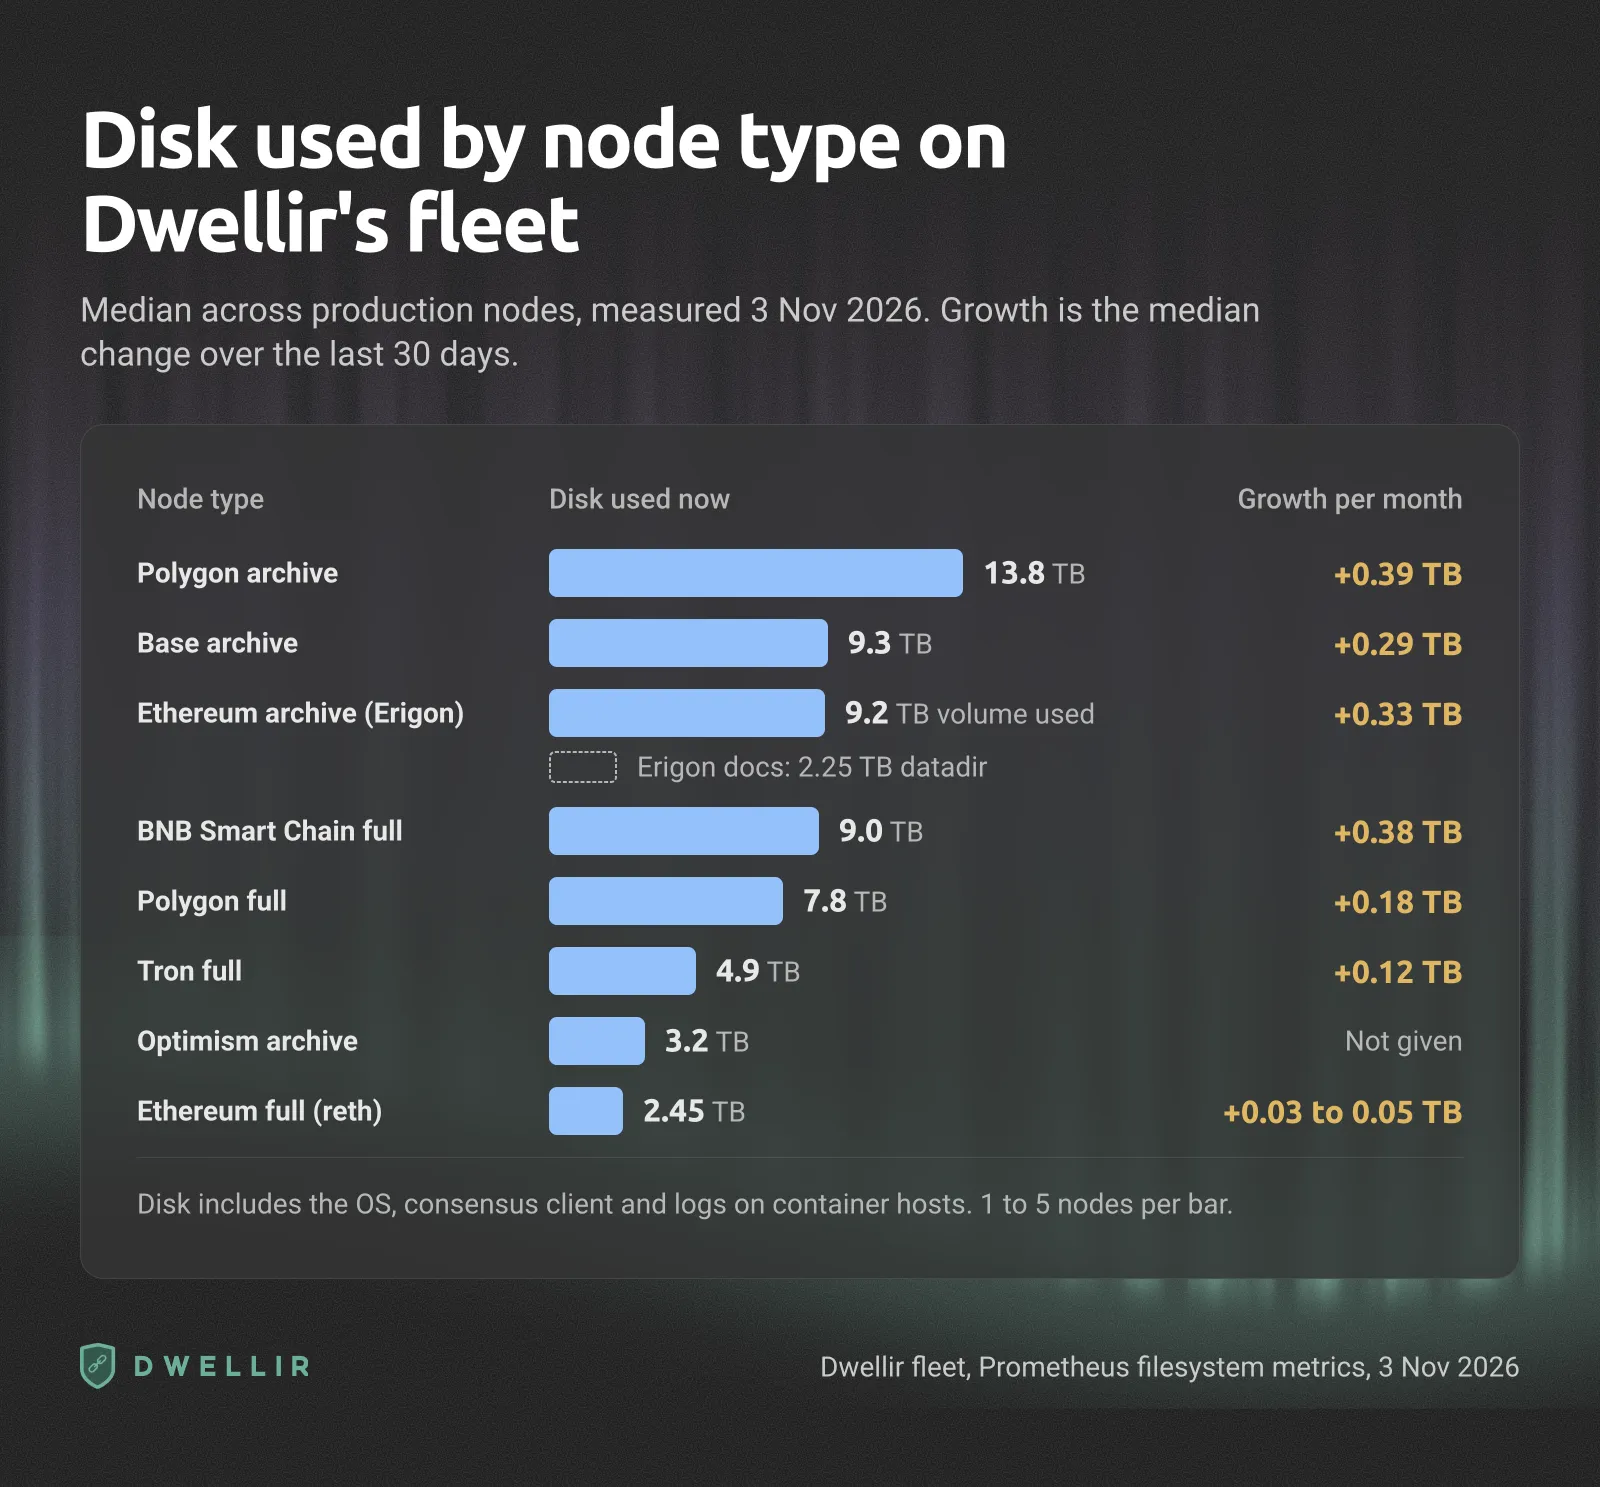
Erigon documents 2.25 TB for an Ethereum mainnet archive datadir (measured September 2026) and recommends a 4 TB drive; the volumes our four Erigon v3 archive nodes run on hold 9.2 TB (median, November 2026) and gain about 0.33 TB per month, and we have not yet measured how much of that is the Erigon datadir.
The 9.2 TB covers everything on each node's volume, including the consensus client, logs and OS, and those alone do not explain a gap of about 7 TB. For what archive access costs beyond the disk, see the hidden costs of archive nodes.
How much disk does an Ethereum full node need?
A pruned Ethereum full node on reth uses 2.45 TB on Dwellir's fleet and grows 1 to 2 GB per day, so a 2 TB drive is already too small. This figure comes from one node.
How fast does a BSC node grow?
A BNB Smart Chain full node on BNB Chain's geth client uses 9.0 TB on Dwellir's fleet and grows about 0.38 TB per month, or about 13 GB per day, measured across 5 nodes.
How big is a Base archive node?
A Base archive node on op-reth uses 9.3 TB on Dwellir's fleet and grows about 0.29 TB per month, or about 10 GB per day, measured across 5 nodes.
We do not run pruned Base full nodes yet, so we have no measured figure for them. Base's performance tuning guide recommends at least 32 GB of RAM (64 GB recommended), a modern CPU with 8 or more cores, and a locally attached NVMe drive.
How much storage does a Polygon node need?
A Polygon full node on Bor uses 7.8 TB on Dwellir's fleet and grows about 0.18 TB per month. A Polygon archive node uses 13.8 TB and grows about 0.39 TB per month.
All measured chains
We read Prometheus filesystem and memory metrics from 32 nodes that serve production traffic. Disk is used space (size minus available) on the filesystem that holds the node: the container root on our LXD sites, which also holds the OS, consensus client and logs (usually under 100 GB together), or the data mount on bare-metal hosts. Each value is the median across nodes of a one-day average, in decimal TB. Growth is the median change over the last 30 days, cross-checked against a linear fit over up to 90 days. RAM in use is total memory minus available memory, so it leaves out page cache. Erigon and reth map their databases into memory and need RAM for cache beyond the figure shown, which is why the allocated amount is listed too. Samples are small: 1 to 6 nodes per row, and the median of two nodes is their midpoint. A pruned node serving less traffic than ours will need less disk and CPU.
| Chain | Node type | Client | Disk used now | Growth per month | RAM in use (allocated) | Nodes measured |
|---|---|---|---|---|---|---|
| Ethereum | Archive | Erigon v3 | 9.2 TB volume used (8.9 to 9.5) (5) | 0.33 TB (about 11 GB/day) | 41 GB (64 GB) | 4 |
| Ethereum | Full (pruned) | reth | 2.45 TB | 0.03 to 0.05 TB (1 to 2 GB/day) | 23 GB (96 GB) | 1 |
| Base | Archive | op-reth | 9.3 TB (9.1 to 9.6) | 0.29 TB (about 10 GB/day) | 20 GB (67 to 256 GB) | 5 |
| Optimism | Archive | op-reth | 3.2 TB (3.1 to 3.2) | Not given (1) | 6 GB (64 to 128 GB) | 2 |
| BNB Smart Chain | Full | BNB Chain geth | 9.0 TB (8.9 to 9.4) | 0.38 TB (about 13 GB/day) | 53 GB (128 to 137 GB) | 5 |
| Polygon | Full | Bor | 7.8 TB (7.8 to 8.2) | 0.18 TB (about 6 GB/day) | 22 GB (48 to 128 GB) | 3 |
| Polygon | Archive | Bor and Heimdall | 13.8 TB | 0.39 TB (about 13 GB/day) (2) | 31 GB (137 GB) | 2 |
| Tron | Full | java-tron | 4.9 TB (4.6 to 5.2) | 0.12 TB (about 4 GB/day) | 14 GB (40 GB) | 2 |
| Sui | Full | sui-node | 0.9 and 5.7 TB | Not given (3) | 27 GB (128 GB), one node | 2 |
| Hyperliquid | Non-validator | hl-node | 0.5 TB (0.46 to 1.25) | Not given (4) | 44 GB (134 to 202 GB) | 6 |
Notes on the table:
- Optimism: one archive node dropped from 4.2 TB to 3.2 TB and the other from 3.4 TB to 3.1 TB in the seven days before the measurement. It looks like a storage format migration in reth, which we have not confirmed for these two nodes, so a monthly rate would mislead.
- Polygon archive: both nodes were restored from a snapshot in September 2026, so growth uses only the last 30 days.
- Sui: both nodes lost about 5 TB to pruning in the week before the measurement. Disk on Sui depends on pruning settings more than on chain age.
- Hyperliquid: hl-node prunes its data continuously, so disk tracks the retention window, not chain history. The 0.5 TB nodes keep about 3 hours of data, after disks once filled at about 100 GB per hour. Our nodes with longer retention hold 4 to 13 TB. Historical Hyperliquid data lives in a separate archive, not on these nodes.
- Ethereum Erigon archive: the figure is the used space on the whole volume each node runs on, not the Erigon datadir. Erigon documents 2.25 TB for the datadir; we have not yet measured how the 9.2 TB splits.
Two configurations are left out of the table on purpose. Our two Ethereum reth archive nodes use 3.8 TB and 9.9 TB, and one grows 0.74 TB per month while the other grows 0.06, so a median of the two would describe neither. A Storage V2 migration is in progress across our reth nodes, which is one reason their sizes differ. Arbitrum One has no row because we measured it separately, on 6 November 2026. Our archive nodes use 4.4 TB, plus 0.7 to 1.4 TB for the Arbitrum Classic node. Sync times are not in the table either. We have very few clean timings on record (see sync time is downtime below).
A few chain-specific details stand out.
Solana figures here are vendor guidance, not our measurement. Dwellir does not run Solana RPC nodes. The Agave hardware recommendations ask for 16 cores and 32 threads or more for an RPC node, 512 GB of RAM or more to keep all account indexes, and separate NVMe drives for accounts (1 TB or larger), ledger (1 TB or larger) and snapshots (500 GB or larger). Agave also warns that running a node on cloud VMs "requires significantly greater operational expertise".
Disk fills faster than client minimums suggest. A BNB Smart Chain node at 9.0 TB on a 10 TB volume is full in under three months at 0.38 TB per month. The archive nodes on Ethereum, Base and Polygon add 0.29 to 0.39 TB per month, about 3.5 to 4.7 TB a year. Syncing BNB Smart Chain from genesis is impractical: start from the latest snapshot and plan storage expansion from day one.
L2 nodes have hidden dependencies. Arbitrum, Optimism, and Base all require access to an L1 Ethereum RPC endpoint. If you self-host the L2 node, you either self-host an Ethereum node too (doubling your infrastructure) or pay a managed provider for L1 access - creating a hybrid setup whether you planned for one or not.
Configuration matters as much as client choice. Erigon documents 2.25 TB for an Ethereum archive datadir, while our two reth archive nodes on the same chain use 3.8 TB and 9.9 TB. Pruning flags, storage format and how long a node has run since its last resync move disk usage by several terabytes. Measure your own node after the first month before you buy the next drive. If you would rather not size and resize these volumes yourself, Dwellir runs the same node types as dedicated node clusters.
Bandwidth and Networking
Teams focus on storage and compute, but bandwidth is a significant cost driver:
- Ethereum: 30-40 TB/month of network transfer
- Solana: Agave asks for a 1 Gbit/s symmetric connection for an unstaked node such as an RPC node, and at least 2 Gbit/s (10 Gbit/s recommended) for a staked validator (Agave docs)
- BNB Smart Chain: High bandwidth due to data volume
On cloud providers, egress charges add up quickly. AWS charges $0.09/GB for outbound data transfer in many regions. At 30 TB/month, that is $2,700 in bandwidth alone - before compute or storage costs.
Bare metal providers like Hetzner include generous or unlimited bandwidth, which is one reason they are popular for node hosting. But they come with other trade-offs: limited geographic distribution, less flexible scaling, and longer provisioning times.
The Operational Reality
Hardware is the straightforward part. Ongoing operations are where self-hosting costs compound.
Client Updates and Hard Forks
Ethereum averages 2 major forks per year plus monthly minor client releases. The Pectra upgrade in May 2025 required all operators to update both execution and consensus layer clients before a hard deadline. Missing a fork means your node follows a dead chain, and your applications read incorrect state - silently.
Every chain has its own upgrade cadence. If you run nodes for 5 chains, you are tracking 5 different release schedules, testing 5 different client updates, and coordinating 5 different upgrade windows.
Monitoring Requirements
A node that appears healthy might be falling behind the chain tip, losing peers, or serving stale data. At minimum, you need to monitor:
- Block lag: How far behind the chain tip is your node?
- Peer count: Is the node maintaining healthy connections?
- Disk space: How close are you to capacity?
- RPC latency: Are response times degrading?
- RAM and CPU utilization: Is the node under resource pressure?
- Sync status: Has the node fallen out of sync?
Most teams use Prometheus for metrics collection and Grafana for dashboards and alerting. Setting this up properly takes days, and maintaining it is ongoing work.
Failover and Redundancy
A single node is a single point of failure. Any maintenance window, client update, or hardware issue means downtime for every application depending on that endpoint.
Production deployments require at minimum 2 nodes behind a load balancer (HAProxy or Nginx). Serious production environments run 3+ nodes across geographic regions. Each additional node multiplies hardware costs and operational complexity.
Sync Time Is Downtime
When a node needs to re-sync after a crash, data corruption, or major upgrade, it is unavailable for the duration. Published sync times are best cases measured on a single clean machine. Erigon's documentation reports about 14 hours 20 minutes to sync an Ethereum archive node from an empty datadir on Erigon 3.6.1, on one test machine with a 400 Mbps download cap.
Our own records are estimates, not stopwatch timings. When we resynced an Ethereum Erigon archive node in February 2026, the OtterSync snapshot stage alone was estimated at about 2 days, and the ticket does not record when the full sync finished. Two Polygon archive nodes restored from snapshot in September 2026 needed 5 to 10 hours per snapshot download, one restore had to be repeated because the first snapshot was not an archive, and both nodes then had about 300,000 blocks to catch up.
During that period, you need fallback infrastructure or your application goes dark.
The Real Cost of Self-Hosting
Hardware pricing is straightforward. Total cost of ownership is harder to calculate because the largest line item is not hardware - it is people.
Hardware Costs
| Provider Type | Monthly Cost | Notes |
|---|---|---|
| Bare metal (Hetzner-class) | $250-750 | Best value for single-location deployments |
| Cloud (AWS/GCP) | $300-800 | Ethereum full node; archive $1,500+/month |
The DevOps Line Item
A blockchain DevOps engineer in the US averages $147,524 per year - about $12,300 per month. Even if node operations represent only 20-30% of that person's role, the prorated cost is $2,000-4,000 per month.
This single line item often exceeds all hardware costs combined, and it is the most commonly underestimated cost when teams evaluate self-hosting.
Total Cost of Ownership by Scenario
| Scenario | Hardware/Month | DevOps (Prorated)/Month | Total/Month |
|---|---|---|---|
| Single ETH full node | $150-300 | $2,000-4,000 | $2,200-4,400 |
| ETH + 2 redundant nodes | $450-900 | $12,000-17,000 | $12,650-18,400 |
| ETH archive + redundancy | $3,000-6,000 | $12,000-17,000 | $15,500-24,000 |
| Multi-chain (5 chains, 2x redundancy) | $2,000-5,000 | $12,000-17,000 | $14,500-23,500 |
The jump from "single node, part-time management" to "production with redundancy" is dramatic. Adding redundancy and archive access pushes costs from $2,200-4,400/month to $15,500-24,000/month - almost entirely due to the dedicated DevOps engineer required at that scale.
For a deeper analysis of archive node costs specifically, see The Hidden Costs of Archive Nodes.
How Managed Providers Work
Managed RPC providers run node infrastructure on your behalf. You get an API endpoint and pay based on usage - either per request, per compute unit, or through a subscription tier.
Architecture
Most managed providers operate node clusters behind load balancers across multiple regions. Your application sends an RPC request, the provider routes it to the nearest healthy node, handles failover automatically, and returns the response. Client updates, monitoring, storage expansion, and redundancy are the provider's responsibility.
From your application's perspective, the endpoint is a single URL. The infrastructure complexity behind it is invisible.
Pricing Models
Your pricing model determines actual cost more than the base rate. Here is how major providers structure billing:
| Provider | Model | Entry Price | How It Works |
|---|---|---|---|
| Alchemy | Compute Units | Variable | Methods cost 10-26+ CUs each; opaque multiplier formula |
| Infura | Credits | $50/month | ~$8.89 per million eth_call requests |
| QuickNode | Credits | $49/month | Method multipliers redesigned in 2024; variable by method |
| Chainstack | Request Units | Variable | 1 RU for full node calls, 2 RU for archive; Unlimited Node add-on available |
| Dwellir | 1:1 credits | $49/month | 1 response = 1 credit; all methods same price including trace/debug |
| dRPC | Flat rate | $49/month | Pro covers ~10M requests ($4.80/M); $6/M overage or pay as you go; less tooling |
Compute unit billing is the primary developer pain point with managed providers. When eth_call costs 1 unit but debug_traceTransaction costs 26 units, forecasting monthly spend becomes a spreadsheet exercise. Dwellir's 1:1 credit model - where every method costs exactly 1 credit - eliminates this complexity. For a detailed comparison, see RPC Providers Without Compute Units.
SLA Expectations
Most managed providers offer 99.9% uptime SLAs on paid plans, with enterprise tiers reaching 99.99%. Achieving equivalent uptime with self-hosted infrastructure requires 3+ nodes across multiple regions with automated failover - the $15,000-24,000/month scenario from the TCO table above.
Managed providers are not immune to outages. The AWS outage in October 2025 took down Coinbase, Robinhood, Infura, and Base simultaneously. Infura's 2022 geoblocking incident accidentally blocked Venezuelan users. Relying on any single provider - managed or not - creates concentration risk.
TCO Comparison: Self-Hosted vs Managed
The following comparison maps self-hosted costs against managed provider costs at different scale levels. Managed costs use Dwellir's pricing (Developer $49/25M credits, Growth $299/150M, Scale $999/500M) as a baseline, with notes on how compute-unit providers compare.
Low Volume: Up to 25 Million Requests/Month
| Cost Category | Self-Hosted | Managed (Dwellir) |
|---|---|---|
| Infrastructure | $150-300/month | $49/month |
| DevOps (prorated) | $2,000-4,000/month | $0 |
| Monitoring/tooling | $50-100/month | Included |
| Redundancy | Not practical at this budget | Included |
| Total | $2,200-4,400/month | $49/month |
At low volumes, self-hosting is economically irrational. The DevOps overhead alone is 45-90x the managed provider cost.
Medium Volume: 150 Million Requests/Month
| Cost Category | Self-Hosted | Managed (Dwellir) |
|---|---|---|
| Infrastructure (2 nodes) | $450-900/month | $299/month |
| DevOps (prorated) | $4,000-8,000/month | $0 |
| Monitoring/tooling | $100-200/month | Included |
| Redundancy | Included (2 nodes) | Included |
| Total | $4,550-9,100/month | $299/month |
The gap narrows in relative terms as volume increases, but self-hosting remains 15-30x more expensive due to operational costs. With compute-unit providers like Alchemy, 150M requests/month with a typical method mix costs $2,000-5,000/month - cheaper than self-hosting, but significantly more than flat-rate alternatives.
High Volume: 500 Million Requests/Month
| Cost Category | Self-Hosted | Managed (Dwellir) |
|---|---|---|
| Infrastructure (3+ nodes, multi-region) | $2,000-5,000/month | $999/month |
| DevOps (dedicated) | $12,000-17,000/month | $0 |
| Monitoring/tooling | $200-500/month | Included |
| Total | $14,200-22,500/month | $999/month |
At high volume, per-request costs from managed providers become highly competitive. Dwellir's Scale plan works out to $1.96 per million requests. A comparable setup with Alchemy costs roughly $5,076/month, and QuickNode roughly $2,789/month, depending on method mix and multipliers.
Extreme Volume: Billions of Requests/Month
At the billions-of-requests scale, dedicated node clusters become the relevant comparison:
| Cost Category | Self-Hosted | Managed Dedicated (Dwellir) |
|---|---|---|
| Infrastructure | $5,000-15,000/month | From $875/month per cluster |
| DevOps | $12,000-17,000/month | $0 |
| Total | $17,000-32,000/month | Custom pricing |
At extreme volumes, economics depend heavily on specific requirements. Dedicated node clusters from providers like Dwellir start at $875/month and scale based on chain, redundancy, and throughput needs. Self-hosting becomes competitive at this scale only if you already have a dedicated infrastructure team and deep operational expertise on a single chain.
When Self-Hosting Makes Sense
The cost analysis favors managed providers in most scenarios, but self-hosting is the right choice in specific situations:
Regulatory and data sovereignty requirements. Some jurisdictions require that blockchain data processing occurs within specific geographic boundaries. If your compliance framework mandates that no third party touches your RPC traffic, self-hosting may be the only option.
MEV operations requiring sub-30ms latency. Competitive MEV extraction demands co-located infrastructure with single-digit millisecond latency to validators. Some managed providers offer co-location, but the most latency-sensitive operations benefit from fully controlled infrastructure.
Custom node configurations. If you need modified client software, non-standard RPC methods, or experimental features like custom debug_traceTransaction tracers, self-hosting gives you complete control over the node configuration.
Extreme single-chain throughput. When your request volume on a single chain reaches billions per month, the economics of dedicated hardware can shift in favor of self-hosting. This only holds if you already have the DevOps expertise.
Deep expertise in a single chain. If your team has specialized knowledge in operating a specific chain's infrastructure (common in validator operations), the marginal cost of adding RPC service to existing nodes is low.
When Managed Providers Make Sense
For the majority of teams, managed providers are the stronger choice:
Speed to market. Your first RPC call happens in minutes, not days. No sync time, no hardware provisioning, no client configuration. For startups racing to launch, this matters.
Multi-chain requirements. Supporting 5+ chains with self-hosted infrastructure means 5 separate node deployments, each with unique hardware requirements, client software, and upgrade schedules. A managed provider like Dwellir provides access to 150+ networks under a single API key.
Teams without blockchain infrastructure expertise. Blockchain node operations are a specialized skill. If your team's strengths are in application development, smart contracts, or product design, the learning curve and ongoing burden of node operations create a real opportunity cost.
Unpredictable or spiky traffic. Applications with variable request volumes (seasonal DeFi activity, NFT mint events, gaming launches) benefit from pay-per-request models that scale automatically. Self-hosted infrastructure must be provisioned for peak capacity and sits idle during low-traffic periods.
99.99% uptime without redundancy investment. Achieving four-nines uptime with self-hosted infrastructure requires 3+ nodes across regions, automated failover, and 24/7 on-call rotation. Managed providers deliver this as a standard feature of their architecture.
The Hybrid Approach
The choice is not binary. Many production teams combine self-hosted and managed infrastructure to capture the benefits of both.
Pattern 1: Managed Primary, Self-Hosted for Sensitive Operations
Use a managed provider for general RPC traffic and route sensitive operations (large transactions, proprietary trading logic) through self-hosted nodes. This limits the data exposure to third parties while keeping operational burden low for routine traffic.
Pattern 2: Self-Hosted Primary, Managed Failover
Run your own nodes as primary infrastructure but configure a managed provider as automatic failover. When your node goes down for maintenance, upgrades, or unexpected issues, traffic routes to the managed endpoint seamlessly. You get self-hosting control with managed-provider reliability as a safety net.
Pattern 3: Managed for Development, Dedicated for Production
Use shared managed endpoints during development and testing, where cost sensitivity is high and uptime requirements are low. Deploy to dedicated node clusters or self-hosted infrastructure for production. This accelerates development velocity without compromising production quality.
Pattern 4: Fast-Path / Heavy-Path Split
Route latency-sensitive operations (transaction submission, mempool monitoring) through co-located self-hosted nodes and route heavy but latency-tolerant operations (historical queries, analytics, indexing) through managed providers with flat-rate pricing.
Common Self-Hosting Mistakes
Teams that self-host frequently hit the same problems. Avoiding these saves weeks of troubleshooting and thousands of dollars in wasted infrastructure.
1. Undersizing storage without accounting for growth. A pruned Ethereum full node on reth already uses 2.45 TB on our fleet, so a 2 TB drive does not fit it. A BNB Smart Chain full node uses 9.0 TB and adds about 0.38 TB per month, so a 10 TB volume is full in under three months. Provision 2-3x your current requirement and plan for expansion.
2. Using consumer-grade SSDs. Consumer QLC (quad-level cell) SSDs fail within 12-24 months under the sustained write loads blockchain nodes generate. Enterprise NVMe drives with high TBW (terabytes written) ratings are essential. The cost difference is small compared to data loss and a full re-sync.
3. Running without monitoring. A node can fall behind the chain tip and serve stale data without any visible error. Without Prometheus, Grafana, or equivalent tooling, you only discover the problem when users report it. Silent lag is the most common failure mode.
4. Single-node production deployments. Any maintenance, update, or hardware issue takes your only node offline. Production deployments need at minimum 2 nodes with automated failover. The cost doubles, but the alternative is accepting periodic downtime.
5. Ignoring client updates. Missing a hard fork means your node follows a dead chain. Applications read incorrect state, transactions fail, and data integrity is compromised. Subscribe to client release channels and test updates promptly.
6. Treating storage as a one-time purchase. On our fleet an Ethereum full node grows 1 to 2 GB per day, a BNB Smart Chain full node about 13 GB per day, and archive nodes on Ethereum, Base and Polygon 10 to 13 GB per day. Budget for storage expansion as a routine operational task, not an emergency response when your drive hits 95%.
7. Running Solana on cloud VMs. The Agave hardware recommendations ask for 512 GB of RAM or more for an RPC node that keeps all account indexes, and separate NVMe drives for accounts and ledger. Agave warns that cloud VMs require significantly greater operational expertise and that operators who choose them should not expect sympathetic support. Plan for bare metal.
8. Forgetting L1 dependencies for L2 nodes. Arbitrum, Optimism, and Base nodes require L1 Ethereum RPC access to verify state. Self-hosting an L2 without planning for this means either an additional self-hosted Ethereum node or a managed provider subscription. Neither appears in naive cost estimates.
9. No documented runbooks. When your on-call engineer gets paged at 3am because a node is out of sync, they need clear procedures: how to check status, when to restart, when to re-sync, and how to fail over. Without runbooks, incident response is slow and error-prone.
Industry Context
The Node-as-a-Service (NaaS) market reached an estimated $135 million in 2024 and is projected to grow to $318 million by 2032. This growth reflects a clear trend: teams are choosing managed infrastructure over self-hosting.
Recent incidents highlight the risks on both sides of that choice:
- AWS October 2025 outage: Took down Coinbase, Robinhood, Infura, Base, and parts of the Solana ecosystem simultaneously, demonstrating the concentration risk of cloud-dependent providers.
- Infura 2022 geoblocking: Accidentally blocked Venezuelan users, highlighting the sovereignty risk of centralized providers.
- Arbitrum December 2023: A 78-minute outage caused by an inscription surge overwhelmed many self-hosted nodes that lacked sufficient resources.
These incidents reinforce a key principle: no infrastructure model eliminates all risk. The goal is to understand and mitigate the specific risks relevant to your situation.
Conclusion
For most teams, the decision is clearer than it appears.
Self-hosting makes sense when you need complete control over node configuration, must comply with data sovereignty regulations, operate at extreme single-chain volumes, or run latency-sensitive MEV operations. The cost floor is $2,200/month for a single unredundant node and scales quickly to $15,000-24,000/month for production-grade multi-node deployments.
Managed providers make sense for everything else, which covers the vast majority of teams. Multi-chain support, instant setup, built-in redundancy, and zero operational overhead make managed infrastructure the economically rational choice for teams making up to hundreds of millions of requests per month.
Hybrid approaches combine self-hosted control with managed reliability when your requirements do not fit neatly into either category.
Three practical next steps:
- Calculate your actual TCO. Use the tables in this guide to estimate both self-hosted and managed costs for your specific situation. Include DevOps time.
- Start managed, self-host later if needed. Migration to self-hosted infrastructure is always possible once you understand your traffic patterns. Starting managed lets your team ship product while you evaluate long-term infrastructure needs.
- Evaluate pricing models carefully. The difference between compute-unit pricing and flat-rate pricing can be 3-5x at scale. Prioritize providers with transparent, predictable billing.
Frequently Asked Questions
Should I self-host my RPC nodes?
Self-hosting makes sense when you need complete control over node configuration, must comply with data sovereignty regulations, operate at extreme single-chain volumes, or run latency-sensitive MEV operations. For most teams, managed providers are more cost-effective because DevOps overhead alone often exceeds $2,000-4,000 per month.
How much does it cost to run your own blockchain node?
A single Ethereum full node costs $150-300 per month in hardware plus $2,000-4,000 in prorated DevOps time, totaling $2,200-4,400 per month. Production-grade setups with redundancy and archive access scale to $15,000-24,000 per month, compared to $49-999 per month for managed providers like Dwellir.
When should I use a managed RPC provider?
Managed providers are the better choice for teams without dedicated blockchain infrastructure expertise, projects requiring multi-chain support, applications with unpredictable traffic, and any team prioritizing speed to market. A managed provider like Dwellir gives you 99.99% uptime and 150+ networks for $49-999 per month.
What is the difference between self-hosted and cloud RPC nodes?
Self-hosted nodes give you full control over hardware, software, and configuration but require ongoing DevOps investment. Cloud or managed RPC nodes are operated by a provider who handles failover, monitoring, client upgrades, and scaling. The trade-off is control versus operational simplicity and cost.
How much storage does an Ethereum archive node need?
Erigon's documentation lists 2.25 TB for a mainnet archive datadir (September 2026) and recommends a 4 TB drive. The volumes Dwellir's four Erigon v3 archive nodes run on hold 9.2 TB (median, November 2026) and grow about 0.33 TB per month, but that is everything on the volume, not the datadir alone, and we have not yet measured the split.
How fast does a BSC node grow?
A BNB Smart Chain full node on BNB Chain's geth client uses 9.0 TB on Dwellir's fleet and grows about 0.38 TB per month, or about 13 GB per day (median of 5 nodes, measured November 2026). At that rate a 10 TB volume is full in under three months.
Related Resources
- RPC Providers Without Compute Units — Compare RPC providers that use transparent pricing instead of opaque compute-unit billing
- Best Ethereum RPC Providers — Head-to-head Ethereum RPC provider comparison with pricing, latency, and feature analysis
- The Hidden Costs of Archive Nodes — Deep dive into the real costs of running and accessing blockchain archive data
Dwellir provides RPC endpoints across 150+ networks with transparent 1:1 pricing - every method costs 1 credit, including trace, debug, and archive queries. No compute unit multipliers, no hidden formulas.
- Get started: Create your free account (100,000 requests/day)
- Compare plans: View pricing from $49/month for 25M credits
- Need dedicated infrastructure?: Contact the Dwellir team to discuss dedicated node clusters starting at $875/month
- Related reading: The Hidden Costs of Archive Nodes | RPC Providers Without Compute Units